Wednesday, 14 May 2014

Peak Interest: The learning and sharing curve

The interest curve of learning and sharing at work and its eventual peak are partly responsible for higher turnover of staff and reduced productivity if not managed well. 

When you learn and share what you know at work you enjoy it. You also contribute to a very productive environment. However when you no longer learn nor share then you are not enjoying it anymore and become negative and a liability. And then leave. 

About a year ago I read an article that explains everything in this blog post in a much clearer and scientifically researched way with references to specific companies. I haven’t been able to find it again, but when I do I will add a link and note to read it instead.


The problem

When you start a new role you have lots to learn. (Although sometimes you may have too much to learn and you are simply out of your depth and not able to keep you head above water).

At the same time you may have a lot experience and new thinking to share with the others in your team and company.

This learning and sharing is usually very enjoyable and rewarding, and you quickly become more and more productive in your role.

This productivity over time can simplistically be viewed in a graph like this:


However after a while in a role you learn less and less. You have absorbed the majority of the domain knowledge, you know all the people involved, and you are familiar with most of the technology stack (if in a similar line of work as me). 

Your team members and colleagues have already heard most of your experiences and you are starting to even repeat yourself. The rewards for sharing are reduced. So your productivity could be viewed as flattening out:
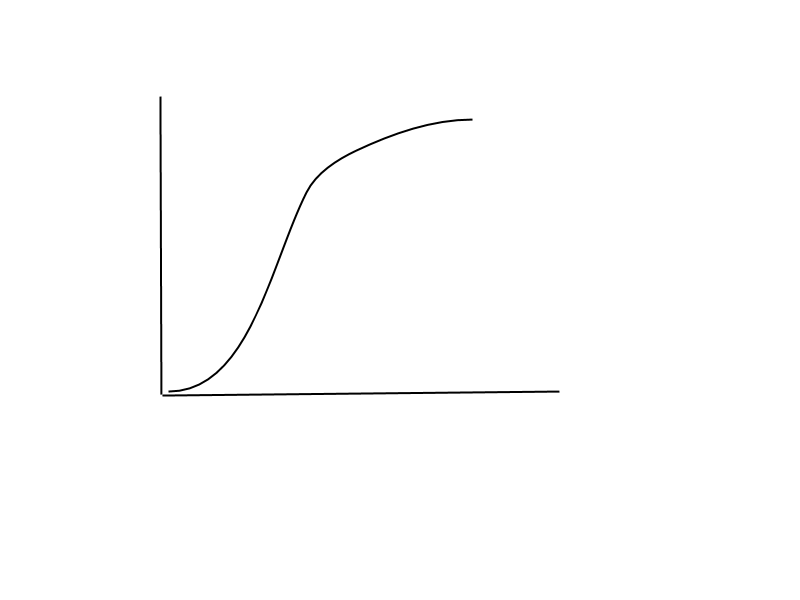

However what tends to happen is that you enjoy your role less due to not learning and not sharing as much as before, and over time you start to not like your role and become quite negative.

This in turn start to have a negative effect on your productivity over time:


This is what I call peak interest.


The consequence

With this negative productivity trend you may start to become negative person at work. This might then spread to your colleague and the whole team starts to suffer.

In the end you probably will change jobs. So the company will have to recommence the expensive recruitment process to replace you and will loose all your knowledge.

Even if you leave quickly it affects the remaining employees negatively. Naturally they might be upset if you leave on a personal level, but also upset with the company for letting you leave, jealous if you leave for a better package elsewhere, depressed that your knowledge and capacity is gone and they have to figure out how to compensate. If many employees leave quickly all the time then the company will have a bad negative culture.


Known problem

This is in fact a known problem, and whilst I can not refer to any scientific research, I have read about this issue many times. 

Major companies are fully aware of these peaks and take many actions to delay and counteract this curve for their employees.


Not applicable to all

The magnitude and curve gradient are definitely different for everyone and for every situation. And not quite as smooth. Some are quicker learners, some in a difficult role, some join a company where there is little to share, etc.

And then there are some sets of people that this hardly applies to at all. The "lifers". Not meant as a derogatory word but I fail to find a better description of this common characteristics of a set of people. 

These are the people that rarely changes jobs, that are not that interested in learning anything new, nor as keen share what they know. They just get on with their job, and stay there for a long while.

Their interest curve whilst perhaps not entirely linear are certainly very much less curved. And may never peak. However my unscientific opinion is that they also make a much less productive contribution to the company over all. 


Every company will have some lifers. There are many roles where this is a good trait: in jobs that are very 9-17 and never really change. 

However it can be frustrating if you mix lifers and “peakers” in the same team. Developers, artists, any creative or knowledge workers need to work together, learn together and share together. If some are then learning and producing at different speeds you will have conflicts.

That being said, mixing peakers with "ninjas" is a recipe for disaster as well. Ninjas and rockstars do not have an interest curve, they have an interest seismograph. But that is for a different blog post.


Solutions

Companies do try to resist and reduce the effect of these peaks. They try to stretch out the length of the peak and create further peaks.

They can ensure the work environment is nice and comfortable. That bureaucracies are not frustrating, latest tools are available and most of all avoid stressful tasks, overtime and other counter productive situations. This will make the peak last longer and post peak decline slower.

Even then the major peak will eventually happen. Companies can then create further peaks by changing team focus, changing project, changing people, changing teams or changing role type completely. Basically avoid status quo for too long.

What they can then achieve is multiple peaks that keep you at a company for much longer.

So this avoids you having to leave the company to find another enjoyable role. However I do think eventually that undulated curve will start to fade and you might leave your role in the end.

The critical bit is then though that instead of leaving after for example 1 to 2 years you might stay for 5 or 8 years. (Time being relative to personality, industry, culture, etc).


Solution faults

Even if the company is aware of interest peaks, and want to mitigate their effects they might not always be able to.

In a small company there might not be any other team or project to move to. In a big company you might be insignificant or just too many to cater for so you are not moved around as often as needed.

Due to deadlines, business restrictions etc there might not be possible to move at the appropriate times.

Different people will have different gradient of curve and peak and companies will struggle to individually predict this.

These might lead to the negative cycle setting root and you resign.


Other issues are of course that changing everything around all the time is not appropriate either. 

It may not be good to do it too often, to do it to too many people at once, to unevenly change roles for some compared to others.  

People and teams do need some sort of stability so constant change is not good either.


Personal experience

I know that I go through these interest curves, and I have especially been taking notice of mine and others lately.

Whilst I do not like to change projects too often as I like to get a thorough knowledge of the domain and project, I know I also need new challenges once I have mastered a domain, technology and/or team to a sufficient level.

When I have worked with startups the curve has always been very steep, the peaks very high, but also the peaks come quickly and the need to change status quo come sooner.

When I worked with large enterprises the gradient was less steep as there was many things that took a long while to do, the technology was less challenging and pace slower. However I also reached the peaks later. But I think the productivity magnitude was much less.

As a consultant these peaks are not so much of an issue due to the normal change of clients and assignments. Some long term clients have even been helpful by moving me to new projects with them in the same assignment although perhaps less on purpose for my benefit, more for their business reasons. 

My beautiful better half reminded my last year when I was moaning about being bored at work. She pointed out that exactly a year before I had told her that I really need to step up my game as there was so much to learn in my new role and that I was loving it. I had clearly reached and passed my peak for that role. 


Conclusion

Peak interest happens to most people and companies. It is nothing to be ashamed about. It is in fact a nice and beneficial trait which needs to be managed.

Company need to embrace interest peaks. Let people move around the company. No questions asked. Encourage it. Better than haemorrhaging good employees, or let a bad vibe fester.

Avoid status quo. For instance make sure technology stack and skills keep continuously evolving even if not always great business value. Staff will stay interested and not need to leave find new challenges.

As an individual if you start to get bored in role, quickly request a change in your role. New project, new technology, new people, new role, whatever it is that will be a nice new challenge.


Disclaimer

Of course productivity and reasons people leave jobs are very much affected by other factors. I do believe however that peak interest of learning and sharing does contribute to both enough for it to be a significant factor.

I do not have any specific scientific research (atm), just a personal opinion backed by reading over time of similar material. If you agree, disagree or have have any research to back it up then feel free to comment or link back.


Saturday, 1 February 2014

Paper Cuts and Broken Windows

It is the little things that matter


We are often reminded of the facts of keeping focus, deliver a minimum viable product, lean startup principles, only invest in what returns business value and so on. Whilst all these are definitely true, but to some extent they are also false.

Delivering business value, concentrating on one task is a virtue I do insist on, however we should not abandon all other tasks and common sense. Secondly it is actually very important we do the low priority and the little ROI tasks as well. Why? Because of Paper Cuts and Broken Windows.   

Note: This may apply to other professions and aspects of life in general but I am only thinking of IT development projects.


TL;DR: Fix your bugs asap, evolve systems continually, keep code clean and take pride in it


The problem: Paper Cuts


Many little bugs that in total hurts a lot.

A paper cut is a simple bug or an outstanding minor feature that is deemed not important enough to fix/implement right now. Some may have best intentions of implementing it soon/eventually but we all know from experience that it is most likely to never happen. 

Over time these paper cuts adds up, soon everything you touch is already full of bugs, painful procedural steps or legacy code, and in the end your team and project may start to venture close to death by a thousand paper cuts or at least feel like it. 


The problem: Broken Windows


If something is already broken, it does not matter if you break something else

Similar to paper cuts, broken windows is when a system/project/code base has some or many things wrong with it so that the current maintainers no longer feel any pride in it. It is then simple to not fix things, to ignore bugs, poor code etc.

If a continuous integration server notification of a broken build or a Nagios alert occurs for that system, people are more concerned about getting rid of the notification than actually fixing the root cause.

In an application suffering from broken windows any new feature will not be done to their best possible standard or refactored for cleaner more maintainable code.  It will not be fully tested, in fact may introduce a few known bugs and limitations that will be ignored.

Also if some epics are never completely finished, it may leave an impression that you do not need to finish stories and epics properly and as such broken windows of missing features start to be an accepted practice.


Combined problem


Essential paper cuts and broken windows are about the same. Paper cuts are how much it is hurting you by slowing you down and making people resistant to do anything with it. Broken windows is about lack of pride and willpower to make an application better as it feels already partially broken.

Or worse, if your customers start to have the same paper cuts and broken windows experience then they will simply stop using the application or even your company.


Derivative problem: The costly rewrite


A system suffering from Paper Cuts & Broken Windows will eventually be so despised by the developers that they will campaign for it to be rewritten from scratch. Which leads to a long period of delivering no business value, just pure expense. Refer to my post: Do Not Rewrite. 

But the new system will eventually also quickly suffer from paper cuts and broken windows if the processes are the same.


Solutions?


There is no right and wrong way to do prevent this. Eventually it is inevitable that a system will suffer from paper cuts and broken windows. However there are several ways to minimise the risk of it happening quickly, increase morale to reduce its spread and significantly delay the rot until the system has been used for so long that there is so little business value left and that it can be shut down.


Prevent death by paper cuts


Fix bugs ASAP


You cannot fix every bug and implement every feature as you will be trying to reach the impossible perfection which would cost an unlimited amount of time and money.

However the cost (in time and therefore money) of fixing a bug increases by magnitudes the longer you leave it, due to the costs of context switch, environment setup, remember data model/logic flow, knowledge share etc. A bug fixed straight away due to a very short feedback loop is invaluable, a bug fixed the same day or next day does take a little time but not much at all. Any longer than that it does become a real exponential costly tech debt.

So try and just fix bugs straight away or at least whilst still on the same specific task. It will make life so much more comfortable. Pushing out buggy features should be deplored.

For minor tasks and bugs that are still skipped or found at a later date they will still cause paper cuts.  A thorough automated and manual QA procedure will reduce this but they will still occur. 


Fix old bugs continually


However I have found continually picking up a few of these left over bugs and tasks will slowly reduce the amount of them on the backlog and therefore help prevent too many paper cuts.

When finishing a large complex story, try to pick up 1 or 2 bugs and minor tech debts before the next big story is started. If you finish another feature an hour before lunch, meeting or end of the day then instead of half starting another story fix a quick bug instead. This continuous self healing done in what is usually mostly lost productivity time will be invaluable over time. It is a beneficial minor procrastination.

If it turns out that bug/feature is a much larger task than you have time for now then simply just add that information to your issue tracker so that at least you have done some backlog grooming that makes it future planning easier. It may then be a valid candidate for one of the few paper cuts that is never fixed, but at least now with more data.


Development principles


Another way of preventing paper cuts is obviously to never introduce them in the first place. A bug free system does not exist, but you can reduce the frequency and impact of them by applying good procedures, architecture and code style. 

Design a system as simple as possible and writing code that is clean ie KISS and SOLID principles, so that a method, class, application or system only does one thing and is very easy to understand. This significantly reduces the risk of introducing unwanted secondary effects and greatly enhances the ease of maintaining it. 

Applying functional programming techniques such as avoiding mutability of objects and removing state where it is not needed will also reduce risk of unwanted secondary effects or architecture issues when scaling a system.

Designing systems and features using TDD reduces risk of bugs, ensures test coverage and also avoids implementing unnecessary features.

Introducing continuous integration delivers a very quick feedback loop so secondary effects are found whilst the developer are still aware of the context. Avoiding time spent on unintegrated feature branches is also advisable (ie max hours, never days). 


Prevent lack of pride due to Broken Windows


Reducing paper cuts will prevent the broken windows feeling. Applying the principles mentioned above (KISS, SOLID, immutability, TDD, CI, etc) will reduce the risk of broken windows. And by insisting on the same principles of good code standards and sensible processes people will take more pride in their work.

But broken windows will happen. Due to unpreventable technology evolution, staff turnover and lack of knowledge transfer or just plain mistakes. 


How do you fix these “windows” and when?


However windows can be fixed. And with more and more windows fixed people take pride in their systems and their work again.

Embrace automation and continuous delivery. If most parts of the process of maintaining a project is automated then any barrier to take the time and energy to fix a broken window will be very low and much more likely to happen voluntarily. 

I wrote a post about a project I was on where we transformed most of what we routinely did into one button clicks on our CI server. The returned value of that investment was great, most tasks was no longer a chore, removed many bottlenecks, the risk of process typos or forgotten steps was minimised and business value feature delivery time was reduced immensely.

A good practice is to apply the same principle of picking up and fixing a broken window issue as you do with bugs, ie as soon as possible or just after finishing another story.

Another practice is to fix issues as part of story, especially if it touches the same areas. If for example a deploy often fails on a server, when you deploy to that server just fix it properly. Do not continue with your head in the sand. 

With these you will slowly mend your most of your broken windows.


Little known time sinks  


It is the little used and little known applications and features that becomes major time sinks when changes are needed. And as such is also the parts the team will avoid to fix. Try to prevent these from becoming this by always evolving architectures and killing features.


Evolve systems


Create your architecture from the start or bit by bit of an existing system into modularised projects and components. That way you can refactor and improve one small part at the time without big and long costly rewrite committal periods of no business value, as detailed in Do Not Rewrite. 

Do not leave old systems to rot with outdated technologies and ever shrinking pool of possible maintainers. Keep evolving it, especially their integration points by for example by applying Micro Service Architecture and/or Strangler Application pattern.


Trim the fat, kill features


If an existing feature is no longer really needed, then be quick to kill it. Euthanasia to unimportant or historic features will make maintenance much easier, reduce risk and speed up delivery of new business value features.

Kill entirely an old application if nearly all its original features have already been migrated away or removed.


Bandwidth


To be able to do this you need the time to do this.

You need a strong tech lead to insist on the team to fix bugs and remove tech debt continuously, and can protect his team if they are pressured to cut corners.

You need non blinkered, smart product owner and/or project manager that understands the long term value of not doing the short term features only. A PO/PM that values the velocity of feature counts only and accepts bandwidth is also used on tech debt to achieve this. The PO/PM should not micromanage tasks and tech debt, only priorities at the epic and story level.

Henrik Kniberg’s Lean from the Trenches book describes the value of feature count above any other metric, and whether you solve tech debt (or not) and how much is up to the team and no-one else.


Summary


To reiterate the TL;DR at the top: Fix your bugs asap, evolve systems continually, keep code clean and take pride in it.


Friday, 8 November 2013

Pair with people you like and code reviews with people you don't like

Pair with people you like and code reviews with people you don't like (misquoted from someone way smarter than me).

That sums it up very well for how I feel about both practices.

With large teams, especially if distributed or partially outsourced, code reviews can ensure code quality and are quite essential. It will allow you to share some knowledge and instill best practices. It will be a reminder for people that their code will be viewed by others so don’t take shortcuts.

However code review can also be a total bottleneck if over-bureaucratic. It will add an overhead for all work. If there are some high and mighty gate keepers that will stop you from pushing your code frequently then you have a complete velocity block. If your code is shit then fair enough, but if it is merely nit picking or just disagreements between styles then it is very costly. If however if any compulsory reviewer is not in your office, country, time zone or just very busy then that adds a large delay in the feedback loop.

Another issue with code reviews is that quite a few reviews are of low quality due to lack of context. They do not necessarily know all the discussions, history of why a piece of code works this way, project code style, etc. Especially if they are of the tainted ivory tower architect affliction.


In smaller, agile and especially collocated teams code reviews will flag issue unnecessarily late in the process. Just pair from the start instead to ensure no short cuts or dodgy code slips through, and automatically spread the knowledge. If you do not trust two of your developers combined then you do have a serious problem.

You can though in addition have small and short swarming/tripling/quadrupling sessions in front of 1 computer to look at especially important issues when they are worked on, not afterwards.

If you do neither code reviews nor pairing then you are in trouble.

Expanded from my own Hacker News comment https://news.ycombinator.com/item?id=6693064

Thursday, 7 November 2013

Don't hire me

There are many reasons not to hire me


I will say no, a lot. I am pragmatic and may find a better solution by asking what it is you actually want to achieve. Or just No

I will say its crap if it is, immediately

I will have an opinion, always. Even when based on very little facts. Sorry

I will change my opinion 180 degrees quickly if a good team convinces me I am totally wrong. This happens a lot, thankfully

If obedience is important to you don't hire me


I am in no way politically correct (not an excuse to be an asshole either) and I make terrible jokes and often “too soon”

I do not have a filter for whom to sugar coat a situation to. I will say the same whether you are a team member, manager, CEO, client or shop keeper. And always blunt and honest

I will be honest with estimates. As in they are total guesswork and only worth it to gage magnitude

If you prefer polite sales type people that tell white lies or total tales then I am not your man


I don’t clock in, I’m definitely not a morning person. If you value timeliness above value then I am not your man

I don’t clock out on the dot either but I rarely work overtime and never weekends. Too risky, if the TPS reports can't wait, don't hire me

I like collaborating, pairing, even tripling for important decisions that needs swarming

I like the team taking ownership together, I detest micro managed task delegation

If you need bums on seat and each task accountable to a person then don’t hire me


I will not jump up like a lap dog when people panic, I barely got a pulse at the best of times. If you prefer knee jerk reactions don't hire me

If you want me to be an ivory tower architect, don't. I like to work with the team to find out their best suggestion is and then work with them to implement it

Or if you have another architect of an ivory tower inclination telling me how to implement something - not going to happen

If you want to keep status quo don’t hire me, I will insist on continual evolutionary improvements. Otherwise the systems will rot, become a big ball of risk and your best developers will leave


However if you want a ninja/rockstar, I am not

If you want me to work with a ninja/rockstar I rather not. Some are okay, but most are a PITA and imperceptibly costly for the company


Insist on Windows? Don’t be ridiculous. No serious developer would accept that handicap unless desperate

Shirt & tie? No, not happening. You can’t take techies dressed as used car salesmen seriously

If you prefer drones in suites, that is not me


Many of these are valid reasons not to hire me

Some I hope are reasons to hire me

Your call


Tuesday, 1 October 2013

Need to ask what each member of your team is doing? Then your team is too big!

In daily (or more frequent) stand ups that is common in agile/scrum based teams many practices the process of asking each and every attendee: what did they do yesterday, will be doing today and if there is any impediments. Many do this by default without considering alternatives.

I have previously blogged that I trust my team members and do not need to know in detail what they did yesterday. I firmly believe it is more productive to focus on the tasks on the board rather than the individual. If you do not trust every member of your team then you have bigger problems.

However task focused only works with a small “1-2 pizza” team. A small team where everyone knows what everyone is doing, where the scrum master / project manager have full understanding of what tasks is currently in progress if not already obvious from the board.

Once the team grows too large you tend to have too many tasks on the board and people are all working on different perhaps even unrelated  tasks. The other team members, and especially scrum master, cannot keep up with all individual and task statuses so you need to do the token ring quiz.

The ring quiz takes time, and tend to let people’s focus drift away from the stand up and not really listen particularly well to what the others have to say after a while (I am guilty of this frequently), especially if some tasks never involve certain other members.

Also the project comes more inclined to individual tasks and not pairing and swarming together on the same tasks. The risk is then some people can disappear between the cracks or loose focus and your project start to become less efficient and agile.

So if you find you stand ups are leaning towards individual “what-you-did what-you-will-do any-impediments” interrogations then it is a strong smell of having a team that is too big.

(“1-2 pizza” is an analogy of how many can share large pizzas together. In my case 3-5 members is a good size, 8-9 is too big, and more than that is simply not agile)


Saturday, 31 August 2013

One button - The aim - Nearly there


An aim for a development team (and company) is to achieve one button deploys of your applications to all environment.


By achieving that it involves several solutions which in total results several direct and indirect benefits for the company. Benefits such as:


  • Quicker releases of new features
  • Frequent releases of new features
  • Quick and painless rollback of unwanted releases
  • Reliable release process
  • Confidence in testing in different environments
  • Reduced risk in deployments
  • Predictable roadmaps with more stable velocities
  • Less context switching for ops and developers
  • Developer time focused on delivering features instead of on processes


I joined as a Tech Lead at my current company last year. Since then my team, or more appropriately our fantastic Ops/Devops, Tools as well as other teams, have in a year made great strides towards One button deploys. We are more or less there and the company is rewarded more and more with the benefits mentioned above. We have achieved this by doing the following since last year:


Move to Git and internally hosted repository server


Subversion was once great but no longer. Whilst we used git-svn for a while, we eventually fully moved all applications’ source code to Git.


With the addition of first Stash then GitLab we removed a lot of bottlenecks, restrictions and frustrations. Code could be easily referenced without having to check out. Collaboration via Pull requests for code bases you may not be comfortable with. Code review when needed. Forking and creating new projects became instant. Project discovery and general code share became very very easy.


External configuration and one binary


The main applications in my team used to use Maven profiles to build separate binaries for each environment. This was because the configuration was baked in via Maven filters.


This is not great for QA sign off as you basically have different binaries. It also slows down deployment as you have to rebuild the binary all the time. It definitely makes it difficult to rollback releases or investigate older releases as you have to rebuild an older version from scratch. And it makes it very fragile as each machine might build it differently (different JDK, broken local Maven repositories, etc)


Moving to external configuration meant we had one binary that gets promoted through all environment. The one binary gets upload to the repository manager (initially Nexus then later Artifactory). This binary is then downloaded as part of every deploy job.


Changing configuration is a configuration change and no change to the binary.


Configuration in source control and rolled out with Puppet


With external configuration we enhanced reliability by adding these configurations into source control. This also meant configuration change became very easy. Push changes for the environment to Git and it was then automatically sync and rollout via Puppet. This removed a very annoying and typo prone bottleneck.


Production configuration changes are not activated automatically but are rolled out via a single command.


Process automation, Teamcityfy everything...


We aimed to automate as many processes as possible. Our continuous integration server, TeamCity, have a number of automated builds and a whole range of manual jobs.


Testing and building a binary automatically on every check in. Automatic deployment to development servers on successful builds.


  • one button jobs to deploy that binary to other environments
  • one button to tag a release
  • one button to push release binaries to environments
  • one button to create bugfix branch
  • one button to rebuild databases
  • one button to migrate database schemas
  • one button to restart servers
  • one button to test 3rd party APIs and environments
  • one button to run acceptance tests
  • one button to smoke test environments
  • one button to trigger load tests (Gatling)


We did use Fabric directly for deploy tasks but Fabric is now triggered from within TeamCity jobs. Deployinator was nice but we phased it out in preference for all deploys in TeamCity for every environment.


Test separation


There was already an extensive JUnit suite of tests in the applications my team was responsible for. However they were a mix of integration tests masquerading as unit tests which slowed down development and feedback loops.


We relabeled unit test that required frameworks (Spring, Hibernate, etc) or databases as integration tests instead. That reduced our feedback loop time.


We added separate verification builds for just integration test. We separated and migrated 3rd party test to 3rd party libraries. We added stand alone acceptance and smoke tests using Cucumber, Specs2 and Selenium.


Test data


We wrote command line and web applications with Node.js and Spray that quickly create test data and tools that review test data. This sped up development testing and proper QA testing.


3rd party mock applications


Mocking out 3rd party systems or even some internal systems entirely by creating test harness applications in integration environments that pretend to be those systems have speeded up our QA process a lot.


Removed restrictions


Restricting who can commit, run certain jobs or see certain data might sound like a sensible option, but in reality it slows down collaboration. We decided we just trust the majority more than we distrust a minority.


A great benefit was that we opened up all Git repositories to everyone. Anyone can commit, although people less involved in a project prefer to use Pull requests.


Team City jobs can be run by anyone. There is an audit trail, but there has never been an issue of anyone ran a job they should not have. It is a great help if people are in meetings or similar that anyone can push code out to the next environment for example.

Production data for some applications due to PCI and CRB restrictions, production credentials and some production jobs for our critical applications are still restricted but we try to minimise this as well.


Feature toggles


Whilst it is a good practice to keep these toggles to a minimum, adding feature toggles that can be overridden via external configuration has been a good change. We can now quickly disable broken new features. We can dark release features or we can canary release features, then via Git & Puppet enable the feature and it becomes available for all.


Content migration tools


Instead of applying content directly and manually as SQL scripts, or scp/ftp/rsync we started writing tools in Play! to help create data sets of new content, then promote those through environment, cross checking which environment the data is in.


Adding scripts that interact with 3rd party portals was also helpful.


This avoid typos, avoids forgetting to run a script in an environment. And greatly speeds up data migration.


Database migration

Many of our applications use NoSQL solutions such as Cassandra and Redis as some of our flows have to handle millions of interactions, but the core data are still mostly in PostgreSQL.

Whilst we use Flyway and DBDeploy to migrate those database schemas and stub data to some environments, we do not use it all the way to production. This is one area we need to improve.


Environment creation


One element that is important and which our Ops team is just starting to roll out is an internal PAAS/IAAS solution. One button to create a new VM environment or one button to create a database, AWS SQS queue etc. Further enhancements, such as one button to clone an existing VM or database will be nice. 


No button

Obviously there were other enhancements that is not really related to "One button", such as phasing out old legacy Java applications with newer Scala applications by applying Strangler Application pattern, replacing Quartz based batch jobs with Akka and Camel, measuring new features effect with AB testing, monitor applications metrics with Graphite, log analysis via Logstash, etc.


Company profitability


All these combined has made certain part of our development and release process so easy and quick. I am sure we have covertly increased the profitability of our company as we now can release quicker, more frequently, with less broken releases or bugs in general.


Future

We still have a lot of work to do. As mentioned we are not quite there with DB migration and Environment creation. We are experimenting with using Vagrant locally and promoting to environments, ZooKeeper for better configuration change without downtime, etc. Eventually we may achieve most of the ideas behind Continuous Delivery.